Businesses don’t always need a chatbot that can explain things nicely. More often, they need a system that can quickly answer: is this request urgent or not, is this lead hot or cold, is this payment suspicious or normal? No long paragraphs and no “human tone.” Just a decision that can be passed into a CRM, a support desk, a doctor’s portal, or a warehouse system.
That’s exactly why there’s so much momentum around decision models. MarkTechPost reports that after TypeSafe launched Jev on September 15, 2026, at least 20 alternatives appeared in roughly four weeks. And that’s where things get interesting. This is no longer about “talking to AI,” but about giving a model a set of allowed answers and getting back a label, a score, or a yes/no probability.
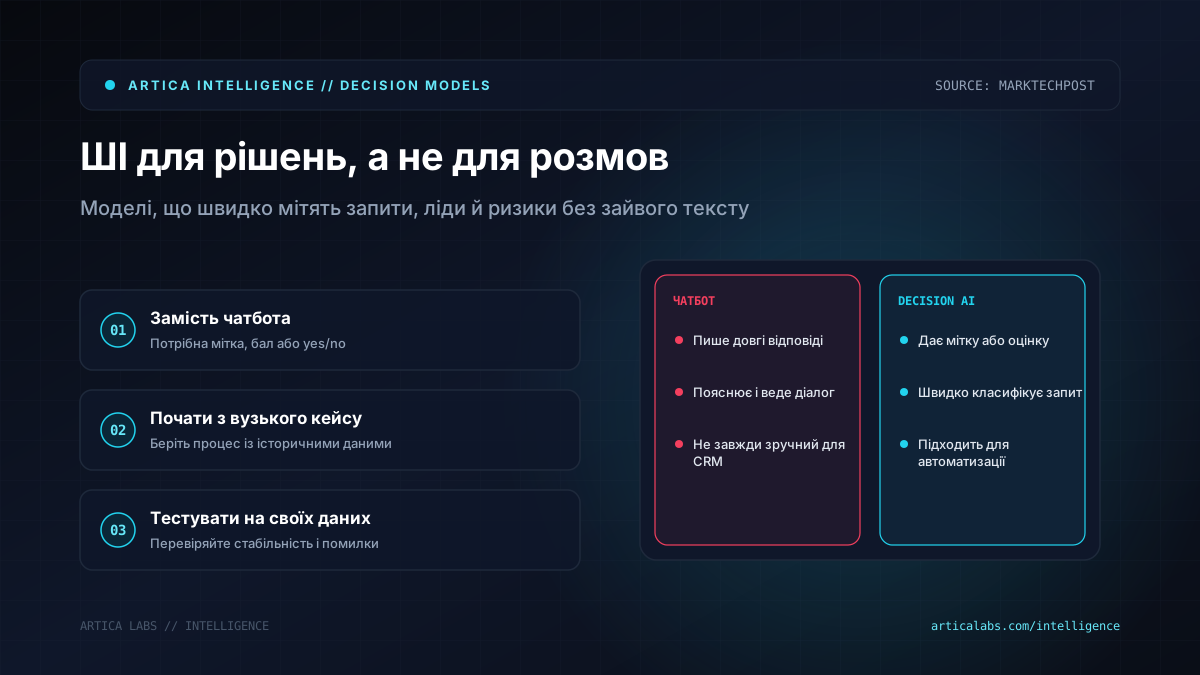
AI that doesn’t chat — it labels
TypeSafe’s Jev works as a model for typed decisions. You pass in a state, say a customer ticket or a log line, and ask a question in a Choice, Score, or yes/no format. The model doesn’t generate text; it evaluates options.
Jev offers a 64k token context window, and the documentation lists pricing at $0.042 per 1 million input tokens, with output free of charge. But there are limitations too: text only, closed weights, access via waitlist, and no published model size, self-hosting, or fine-tuning.
The alternatives are trying to fill those gaps. Cloudflare Clef and Clef-flash run through Workers AI and accept text, JSON, and up to 4 images per request. Perplexity’s pplx-decider reads text, JSON, and up to 8 images per question, while the flash version costs $0.01 per 1 million input tokens. OpenAI has released the Decisions API in public beta, but it is not compatible with the Jev API and has no published benchmarks.
There is also an open-source track. AWS Strands Labs’ Strands Decider can be run locally, Kev comes in variants from 0.8B to 27B, Mapika Decider reaches 35B-A3B, and lighter models such as Von, Laya, or GLiNER2.5-Decide are interesting for CPU or edge use cases. The range is wide: from 287M parameters to 35B-A3B. There’s no single obvious winner anymore. But there’s also no simple “just pick the newest one” answer here.
Where this can actually work in a real workflow
Imagine an online store. The model can sort incoming requests by type: returns, warranty, delivery, complaint. Not answer the customer instead of an agent, but pass a label into the helpdesk and assign a priority.
In a clinic, such a model could pre-classify a patient’s request based on the symptom description and route it to the right administrator. In an agency, it could score leads by purchase likelihood. In a delivery operation, it could flag risky incidents in operational logs.
A practical starting point looks like this:
- pick one narrow process where you already have historical data and correct answers;
- compare 2–3 models on your own sample, not on polished vendor benchmarks;
- check stability: does the answer change if you reorder the options or rephrase the prompt;
- keep a human in the loop where a mistake would be expensive.
The pitfalls are serious. MarkTechPost explicitly notes that most results in the tables are self-reported. In an independent run, Respan Jev posted 0.932 accuracy, Tev1 scored 0.901, Kev 0.833, while Laya and Von dropped noticeably. But that test was also done by the vendor of a competing model. So it’s useful as a reference point — not as gospel.
The biggest risk for businesses is something else: the model returns the result in the right format, but gets the substance wrong. Automation looks clean, reports are generated, the process seems to be working. And then it turns out that hot leads were routed the wrong way, customer complaints got low priority, and suspicious payments went through as ordinary ones.
That’s why decision models are better deployed not as a magic button, but as a controlled layer in n8n, Make, CRM, or internal SaaS. With logs, tests, confidence thresholds, and manual review at the beginning.
Our take is simple: this is a strong tool for operational automation, especially where businesses need decisions rather than text. But you should not buy the model name. Buy the proven result on your own data.