When a business connects an AI agent to the web, the word free sounds very appealing. It feels like this is it: the agent can read competitors’ sites on its own, collect prices, check product availability, and prepare research for a marketer.
Then the bill arrives. And often it isn’t for the search itself, but for what the agent brought back for the language model to read.
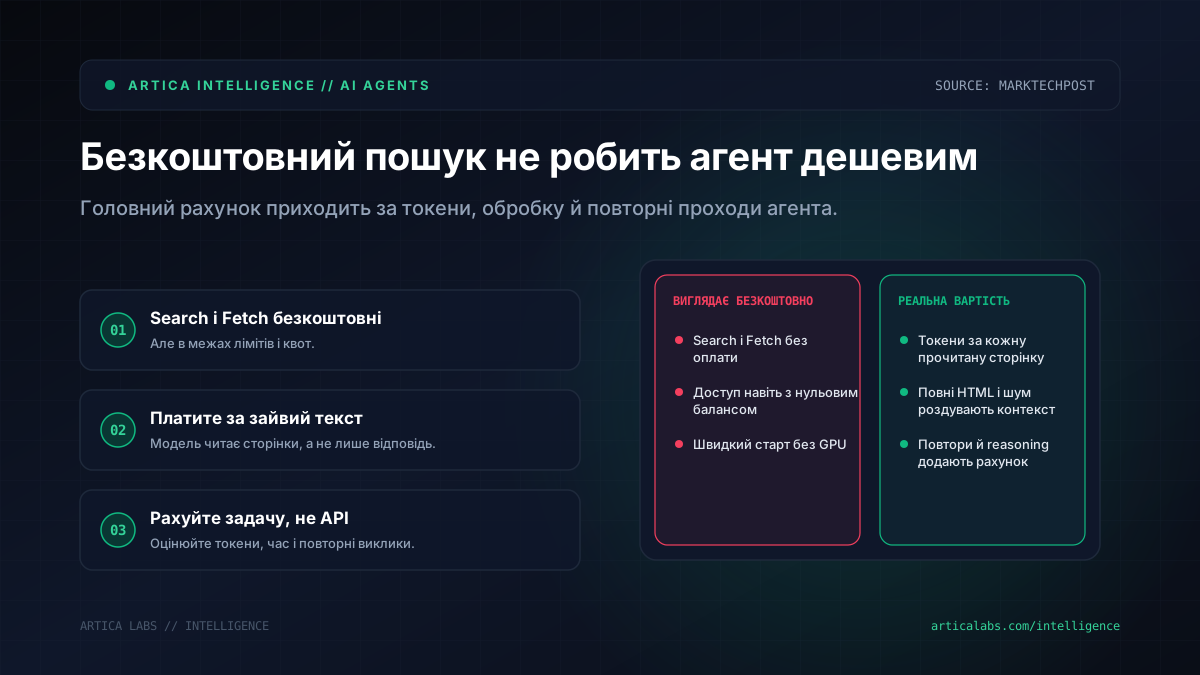
As MarkTechPost writes, TinyFish has made Search and Fetch free within certain limits. But there’s a second part to the economics here: every page the agent reads turns into input tokens for the model. Then you add reasoning, the model’s response, and repeated passes in the agent loop. That’s where things get interesting.
A free request doesn’t automatically make the task cheap
TinyFish now offers free Search within 30 requests per minute and 500 per hour. Fetch is free up to 150 URLs per minute and 1,000 per day. Both work even with a zero Wallet balance.
Access is available through REST, Python and TypeScript SDKs, CLI, and MCP. Under the hood, the company uses its own infrastructure with a browser fleet for rendering pages and interacting with sites. No local GPU is required for this.
In the Artificial Analysis snapshot from September 28, 2026, TinyFish Search scored 71 points and showed $9.30 per 1,000 benchmark tasks, if you count the model component. That’s the lowest total cost among the 12 configurations shown.
But there’s a caveat. The score of 71 was the lowest among the systems shown, while Perplexity Search medium scored 80. TinyFish took 59 seconds per task, which was the second-slowest result in the table. So yes, it’s cheap — but not always fast, and not always the best in terms of quality.
There’s another limitation: in the Agent product, TinyFish’s built-in model cannot be swapped out. For some teams, that’s perfectly fine. But if you want to fine-tune model choices for different tasks, you’ll have to accept that trade-off.
The real money sink isn’t search — it’s extra text
MarkTechPost gives a telling example from a TinyFish test on 45 URLs. For one Daily Mail article with a body of roughly 4,300 characters, different providers returned very different amounts of text.
TinyFish Fetch returned 4,737 characters, roughly 1,184 tokens. Firecrawl Scrape returned 171,095 characters, about 42,774 tokens. Exa Contents and Tavily Extract also returned much more: 65,793 and 46,433 characters respectively. Parallel Extract returned only a short excerpt of 600 characters, so it wouldn’t be fair to compare it directly with full extracts.
That’s one site, not a universal law. But for business, the takeaway is simple: if the agent pulls in menus, comments, ads, footers, and technical noise, you’re paying the model to read junk.
Imagine an e-commerce company that checks competitors’ prices every day. If the agent grabs full product pages without cleaning them up, the context fills up fast. A page with 42,774 tokens takes up about a third of a 128K context window. Three such pages already come to about 128,322 tokens, leaving almost no room for instructions, conversation history, or the answer itself.
We’d start not with the cheapest API, but with a few grounded checks:
- measure the average page size after Fetch: characters, tokens, and the share of useful text;
- don’t send the model full HTML pages if a price, title, description, or table is enough;
- test the provider on your own sites, because news sites, marketplaces, and B2B catalogs behave differently;
- calculate the cost of the task, not the price of a single API request;
- check limits and latency, especially for real-time processes.
For an agency, that may mean cheaper market research. For a clinic, it could be monitoring regulatory updates. For a delivery service, it might mean checking partner pages. The scenarios are normal enough — but we still wouldn’t put this kind of tool into production without a small pilot: 50–100 typical tasks, measured token usage, time, answer quality, and the number of repeated calls.
Free search is nice. But the real savings begin where the agent reads less unnecessary content and extracts what matters more precisely.